Markowitz Portfolio Theory for Crypto: From Zero to Hero
Building optimal crypto portfolios with Python - because YOLO isn't a strategy. Learn how to apply Nobel Prize-winning portfolio theory to crypto investments with practical Python code examples.
Building optimal crypto portfolios with Python - because YOLO isn't a strategy
 Markowitz Portfolio Theory: Mathematical optimization applied to digital assets to maximize returns for a given risk level.
Introduction: Why Your Crypto Portfolio Needs Math (Not Just Vibes)
Hey crypto degens! 👋
Remember that time you threw your entire stack into DOGE because Elon tweeted? Or when you panic-sold everything during the last crash? Yeah, we've all been there. Today we're going to talk about something that might save your portfolio (and your sanity): Markowitz Portfolio Theory.
Harry Markowitz literally won a Nobel Prize for this stuff back in 1990. The basic idea? You can mathematically optimize your portfolio to get the best possible returns for any given level of risk. It's like having a GPS for your investments instead of driving blindfolded.
The Core Concept: Risk vs Return (The Eternal Dance)
Before we dive into code, let's understand what we're dealing with:
- Expected Return: How much money you expect to make
- Risk (Volatility): How much your portfolio value bounces around
- Correlation: How similarly different assets move together
The magic happens when you combine assets that don't move in perfect sync. When Bitcoin crashes, maybe some DeFi tokens hold up better. That's diversification working for you.
 Risk vs. Return: Balancing volatile high-yield assets with a stable foundation to achieve the optimal geometric mean return.
Setting Up Our Python Environment
First things first - let's get our tools ready:
# Essential libraries for our crypto portfolio optimization
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
from scipy.optimize import minimize
import yfinance as yf
import warnings
warnings.filterwarnings('ignore')

# Set up plotting style
plt.style.use('dark_background')
sns.set_palette("husl")
Level 1: Baby Steps - Simple Portfolio Math
Let's start with the basics. We'll calculate returns and risk for a simple 2-asset portfolio.
def get_crypto_data(symbols, period="1y"):
    """
    Fetch crypto data from Yahoo Finance
    symbols: list of crypto symbols (e.g., ['BTC-USD', 'ETH-USD'])
    period: time period for data
    """
    data = yf.download(symbols, period=period)['Adj Close']
    return data

# Get data for Bitcoin and Ethereum
crypto_symbols = ['BTC-USD', 'ETH-USD']
prices = get_crypto_data(crypto_symbols)

# Calculate daily returns
returns = prices.pct_change().dropna()
print("Daily Returns Preview:")
print(returns.head())
Now let's calculate some basic portfolio metrics:
def portfolio_performance(weights, returns):
    """
    Calculate portfolio return and volatility
    weights: array of portfolio weights
    returns: dataframe of asset returns
    """
    # Portfolio return (annualized)
    portfolio_return = np.sum(returns.mean() * weights) * 252

    # Portfolio volatility (annualized)
    portfolio_vol = np.sqrt(np.dot(weights.T, np.dot(returns.cov() * 252, weights)))

    return portfolio_return, portfolio_vol

# Example: 50% BTC, 50% ETH
weights_5050 = np.array([0.5, 0.5])
ret_5050, vol_5050 = portfolio_performance(weights_5050, returns)

print(f"50/50 Portfolio:")
print(f"Expected Annual Return: {ret_5050:.2%}")
print(f"Annual Volatility: {vol_5050:.2%}")
print(f"Sharpe Ratio: {ret_5050/vol_5050:.3f}")
Level 2: Getting Serious - The Efficient Frontier
Now we're cooking! The efficient frontier shows us all possible optimal portfolios. Each point represents the best possible return for a given level of risk.
def generate_random_portfolios(returns, num_portfolios=10000):
    """
    Generate random portfolio combinations
    """
    num_assets = len(returns.columns)
    results = np.zeros((4, num_portfolios))

    for i in range(num_portfolios):
        # Generate random weights
        weights = np.random.random(num_assets)
        weights /= np.sum(weights)  # Normalize to sum to 1

        # Calculate portfolio metrics
        portfolio_return, portfolio_vol = portfolio_performance(weights, returns)
        sharpe_ratio = portfolio_return / portfolio_vol

        # Store results
        results[0,i] = portfolio_return
        results[1,i] = portfolio_vol
        results[2,i] = sharpe_ratio
        results[3,i:] = weights

    return results

# Generate 10,000 random portfolios
results = generate_random_portfolios(returns)

# Create a dataframe for easier handling
portfolio_results = pd.DataFrame({
    'Returns': results[0],
    'Volatility': results[1],
    'Sharpe_Ratio': results[2]
})

# Plot the efficient frontier
plt.figure(figsize=(12, 8))
scatter = plt.scatter(portfolio_results['Volatility'],
                     portfolio_results['Returns'],
                     c=portfolio_results['Sharpe_Ratio'],
                     cmap='viridis', alpha=0.6)
plt.colorbar(scatter, label='Sharpe Ratio')
plt.xlabel('Volatility (Risk)')
plt.ylabel('Expected Return')
plt.title('Efficient Frontier - Random Portfolios')
plt.show()
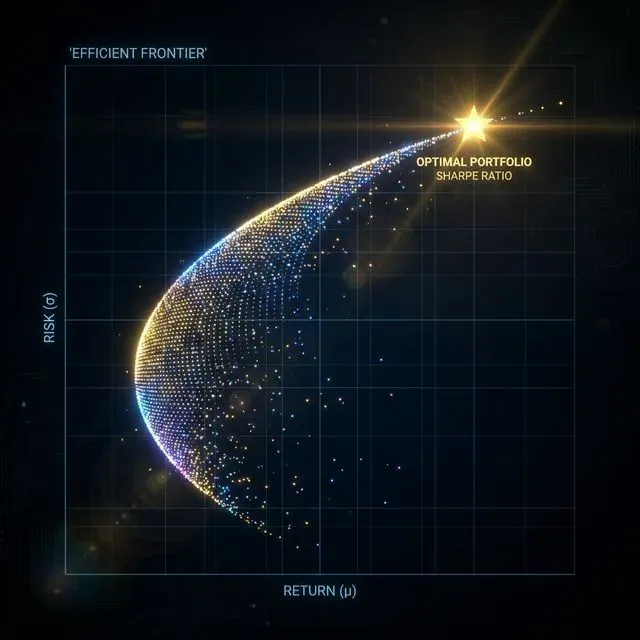 The Efficient Frontier: The curve representing the maximum possible expected return for a given level of risk.
Level 3: Optimization Master - Finding the Perfect Portfolio
Random sampling is fun, but we want the mathematically optimal solution. Time to bring out the big guns - scipy optimization!
def negative_sharpe_ratio(weights, returns, risk_free_rate=0.02):
    """
    Calculate negative Sharpe ratio (we minimize this)
    """
    portfolio_return, portfolio_vol = portfolio_performance(weights, returns)
    sharpe = (portfolio_return - risk_free_rate) / portfolio_vol
    return -sharpe

def minimize_volatility(weights, returns):
    """
    Calculate portfolio volatility (we minimize this)
    """
    _, portfolio_vol = portfolio_performance(weights, returns)
    return portfolio_vol

def portfolio_return_objective(weights, returns):
    """
    Calculate portfolio return (we maximize this)
    """
    portfolio_return, _ = portfolio_performance(weights, returns)
    return -portfolio_return  # Negative because we minimize

def optimize_portfolio(returns, objective='sharpe', target_return=None):
    """
    Optimize portfolio based on different objectives
    """
    num_assets = len(returns.columns)

    # Constraints and bounds
    constraints = ({'type': 'eq', 'fun': lambda x: np.sum(x) - 1})  # Weights sum to 1
    bounds = tuple((0, 1) for _ in range(num_assets))  # No short selling

    # Initial guess
    initial_guess = num_assets * [1. / num_assets]

    if objective == 'sharpe':
        # Maximize Sharpe ratio
        result = minimize(negative_sharpe_ratio, initial_guess,
                         args=(returns,), method='SLSQP',
                         bounds=bounds, constraints=constraints)

    elif objective == 'min_vol':
        # Minimize volatility
        result = minimize(minimize_volatility, initial_guess,
                         args=(returns,), method='SLSQP',
                         bounds=bounds, constraints=constraints)

    elif objective == 'target_return':
        # Minimize volatility for target return
        constraints = ({'type': 'eq', 'fun': lambda x: np.sum(x) - 1},
                      {'type': 'eq', 'fun': lambda x: portfolio_performance(x, returns)[0] - target_return})

        result = minimize(minimize_volatility, initial_guess,
                         args=(returns,), method='SLSQP',
                         bounds=bounds, constraints=constraints)

    return result

# Find optimal portfolios
max_sharpe = optimize_portfolio(returns, 'sharpe')
min_vol = optimize_portfolio(returns, 'min_vol')

print("🎯 Maximum Sharpe Ratio Portfolio:")
for i, symbol in enumerate(crypto_symbols):
    print(f"{symbol}: {max_sharpe.x[i]:.3f}")

ret_sharpe, vol_sharpe = portfolio_performance(max_sharpe.x, returns)
print(f"Return: {ret_sharpe:.2%}, Volatility: {vol_sharpe:.2%}")
print(f"Sharpe Ratio: {ret_sharpe/vol_sharpe:.3f}\n")

print("🛡️ Minimum Volatility Portfolio:")
for i, symbol in enumerate(crypto_symbols):
    print(f"{symbol}: {min_vol.x[i]:.3f}")

ret_minvol, vol_minvol = portfolio_performance(min_vol.x, returns)
print(f"Return: {ret_minvol:.2%}, Volatility: {vol_minvol:.2%}")
Level 4: Multi-Asset Madness - Real Crypto Portfolio
Let's scale this up to a proper crypto portfolio with multiple assets:
# Expand to more cryptocurrencies
crypto_portfolio = ['BTC-USD', 'ETH-USD', 'BNB-USD', 'ADA-USD', 'SOL-USD', 'DOT-USD']
prices_multi = get_crypto_data(crypto_portfolio, period="2y")
returns_multi = prices_multi.pct_change().dropna()

# Check correlations
correlation_matrix = returns_multi.corr()

plt.figure(figsize=(10, 8))
sns.heatmap(correlation_matrix, annot=True, cmap='RdYlBu_r', center=0)
plt.title('Crypto Asset Correlation Matrix')
plt.show()

def efficient_frontier(returns, num_portfolios=50):
    """
    Calculate the efficient frontier
    """
    # Calculate range of target returns
    ret_range = np.linspace(returns.mean().min()*252, returns.mean().max()*252, num_portfolios)

    efficient_portfolios = []

    for target_ret in ret_range:
        try:
            result = optimize_portfolio(returns, 'target_return', target_ret)
            if result.success:
                ret, vol = portfolio_performance(result.x, returns)
                efficient_portfolios.append([ret, vol, result.x])
        except:
            continue

    return np.array(efficient_portfolios)

# Calculate efficient frontier
efficient_port = efficient_frontier(returns_multi)

# Plot everything together
plt.figure(figsize=(14, 10))

# Random portfolios
random_results = generate_random_portfolios(returns_multi, 5000)
plt.scatter(random_results[1], random_results[0],
           c=random_results[2], cmap='viridis', alpha=0.3, s=10)

# Efficient frontier
if len(efficient_port) > 0:
    plt.plot(efficient_port[:,1], efficient_port[:,0], 'r-', linewidth=3, label='Efficient Frontier')

# Optimal portfolios
max_sharpe_multi = optimize_portfolio(returns_multi, 'sharpe')
min_vol_multi = optimize_portfolio(returns_multi, 'min_vol')

ret_sharpe_multi, vol_sharpe_multi = portfolio_performance(max_sharpe_multi.x, returns_multi)
ret_minvol_multi, vol_minvol_multi = portfolio_performance(min_vol_multi.x, returns_multi)

plt.scatter(vol_sharpe_multi, ret_sharpe_multi, marker='*', color='gold', s=500, label='Max Sharpe')
plt.scatter(vol_minvol_multi, ret_minvol_multi, marker='*', color='red', s=500, label='Min Volatility')

plt.colorbar(label='Sharpe Ratio')
plt.xlabel('Volatility (Risk)')
plt.ylabel('Expected Return')
plt.title('Multi-Asset Crypto Portfolio Optimization')
plt.legend()
plt.show()

# Display optimal allocations
print("🚀 Optimal Multi-Asset Allocations:")
print("\nMaximum Sharpe Ratio Portfolio:")
sharpe_weights = pd.Series(max_sharpe_multi.x, index=crypto_portfolio).sort_values(ascending=False)
for asset, weight in sharpe_weights.items():
    if weight > 0.01:  # Only show significant allocations
        print(f"{asset}: {weight:.1%}")

print(f"\nPortfolio Metrics:")
print(f"Expected Return: {ret_sharpe_multi:.1%}")
print(f"Volatility: {vol_sharpe_multi:.1%}")
print(f"Sharpe Ratio: {ret_sharpe_multi/vol_sharpe_multi:.2f}")
 Multi-Asset Diversification: Constructing a robust portfolio by combining uncorrelated crypto assets into a stable geometric structure.
Level 5: Advanced Techniques - Black-Litterman and Risk Parity
For the true portfolio optimization ninjas, let's implement some advanced techniques:
def risk_parity_portfolio(returns):
"""
Risk Parity Portfolio - each asset contributes equally to portfolio risk
"""
def risk_contribution(weights, cov_matrix):
portfolio_vol = np.sqrt(np.dot(weights.T, np.dot(cov_matrix, weights)))
marginal_contrib = np.dot(cov_matrix, weights) / portfolio_vol
contrib = weights * marginal_contrib
return contrib
def risk_parity_objective(weights, cov_matrix):
contrib = risk_contribution(weights, cov_matrix)
target_contrib = np.ones(len(weights)) / len(weights)
return np.sum((contrib - target_contrib)**2)
num_assets = len(returns.columns)
cov_matrix = returns.cov() * 252
constraints = ({'type': 'eq', 'fun': lambda x: np.sum(x) - 1})
bounds = tuple((0.001, 1) for _ in range(num_assets))
initial_guess = num_assets * [1. / num_assets]
result = minimize(risk_parity_objective, initial_guess,
args=(cov_matrix,), method='SLSQP',
bounds=bounds, constraints=constraints)
return result
# Calculate Risk Parity portfolio
risk_parity_result = risk_parity_portfolio(returns_multi)
print("⚖️ Risk Parity Portfolio:")
rp_weights = pd.Series(risk_parity_result.x, index=crypto_portfolio).sort_values(ascending=False)
for asset, weight in rp_weights.items():
print(f"{asset}: {weight:.1%}")
ret_rp, vol_rp = portfolio_performance(risk_parity_result.x, returns_multi)
print(f"\nRisk Parity Metrics:")
print(f"Expected Return: {ret_rp:.1%}")
print(f"Volatility: {vol_rp:.1%}")
print(f"Sharpe Ratio: {ret_rp/vol_rp:.2f}")
def backtest_portfolio(weights, prices):
"""
Simple backtest of portfolio performance
"""
returns = prices.pct_change().dropna()
portfolio_returns = (returns * weights).sum(axis=1)
# Calculate cumulative returns
cumulative_returns = (1 + portfolio_returns).cumprod()
# Performance metrics
total_return = cumulative_returns.iloc[-1] - 1
annualized_return = (1 + total_return) ** (252 / len(portfolio_returns)) - 1
annualized_vol = portfolio_returns.std() * np.sqrt(252)
sharpe_ratio = annualized_return / annualized_vol
max_dd = (cumulative_returns / cumulative_returns.expanding().max() - 1).min()
return {
'total_return': total_return,
'annualized_return': annualized_return,
'annualized_volatility': annualized_vol,
'sharpe_ratio': sharpe_ratio,
'max_drawdown': max_dd,
'cumulative_returns': cumulative_returns
}
# Backtest our strategies
strategies = {
'Max Sharpe': max_sharpe_multi.x,
'Min Volatility': min_vol_multi.x,
'Risk Parity': risk_parity_result.x,
'Equal Weight': np.ones(len(crypto_portfolio)) / len(crypto_portfolio)
}
plt.figure(figsize=(14, 8))
for name, weights in strategies.items():
backtest_results = backtest_portfolio(weights, prices_multi)
plt.plot(backtest_results['cumulative_returns'], label=f"{name} (Sharpe: {backtest_results['sharpe_ratio']:.2f})")
plt.title('Portfolio Strategy Backtests')
plt.xlabel('Date')
plt.ylabel('Cumulative Returns')
plt.legend()
plt.yscale('log')
plt.grid(True, alpha=0.3)
plt.show()
*Algorithmic Backtesting: Simulating historical performance to validate theoretical optimization models.*
# Performance summary table
performance_summary = pd.DataFrame()
for name, weights in strategies.items():
results = backtest_portfolio(weights, prices_multi)
performance_summary[name] = [
f"{results['annualized_return']:.1%}",
f"{results['annualized_volatility']:.1%}",
f"{results['sharpe_ratio']:.2f}",
f"{results['max_drawdown']:.1%}"
]
performance_summary.index = ['Annual Return', 'Annual Volatility', 'Sharpe Ratio', 'Max Drawdown']
print("\n📊 Strategy Performance Summary:")
print(performance_summary)
The Reality Check: What Markowitz Doesn't Tell You
Before you go all-in on mathematical optimization, here are some hard truths about crypto:
1. Past Performance ≠ Future Results The crypto market is young and chaotic. Those correlations you calculated? They might flip overnight when regulations change or when the next big hack happens.
2. Transaction Costs Matter Rebalancing your portfolio costs money. In DeFi, gas fees can eat your lunch. Factor this into your strategy.
3. Liquidity Issues Not all cryptos are equally liquid. That small-cap altcoin might look great in your optimization, but try selling it during a crash.
4. Regime Changes Crypto markets have different "regimes" - bull markets, bear markets, crab markets. What works in one might not work in another.
Practical Implementation Tips
def practical_portfolio_rebalancing(target_weights, current_weights, threshold=0.05):
    """
    Only rebalance when weights drift beyond threshold
    """
    weight_diff = np.abs(target_weights - current_weights)
    needs_rebalancing = np.any(weight_diff > threshold)

    if needs_rebalancing:
        print("🔄 Rebalancing needed!")
        for i, (target, current) in enumerate(zip(target_weights, current_weights)):
            if abs(target - current) > threshold:
                print(f"Asset {i}: {current:.1%} → {target:.1%}")
    else:
        print("✅ Portfolio within tolerance, no rebalancing needed")

    return needs_rebalancing

# Example usage
current_allocation = np.array([0.35, 0.25, 0.15, 0.10, 0.10, 0.05])
target_allocation = max_sharpe_multi.x

practical_portfolio_rebalancing(target_allocation, current_allocation)
Conclusion: Your Portfolio Optimization Toolkit
You now have a complete toolkit for crypto portfolio optimization:
- Basic calculations for risk and return
- Efficient frontier visualization
- Mathematical optimization for different objectives
- Advanced strategies like risk parity
- Backtesting framework to validate your strategies
- Practical considerations for real-world implementation
Key Takeaways
- Diversification is free lunch - the only free lunch in investing
- Optimize based on your risk tolerance - max Sharpe isn't always best for you
- Rebalance systematically but don't overtrade
- Stay humble - models are tools, not crystal balls
- Start simple and add complexity as you learn
Remember: In crypto, even the best mathematical models can't predict when Elon will tweet about Dogecoin or when the next exchange will get hacked. Use portfolio theory as your foundation, but always keep some powder dry and never invest more than you can afford to lose.
Now go forth and optimize responsibly! 🚀
Further Reading
Code Repository
All the code from this tutorial is available on GitHub: https://github.com/suenot/markowitz
Happy optimizing! 📈

